A GENERATED CHALLENGE BANK
How far can an agent
get without the rules?
Pixels, neutral controls, six changing levels. Explore real puzzle mechanics and the gaps left by eleven evaluated model configurations.
Step into the experiment ↓curricula remained unfinished
by every tested configuration.
At the fixed 512-action / 720-second budget.
Two of these tasks yielded zero completed
levels across all eleven configurations.
01 / INTERACT
A real puzzle, in your browser.
The original rules run locally. Explore the numbered controls and watch the pixels change.
Keyboard: 1–6; R resets. For coordinate controls, click a cell on the grid.
02 / COMPARE
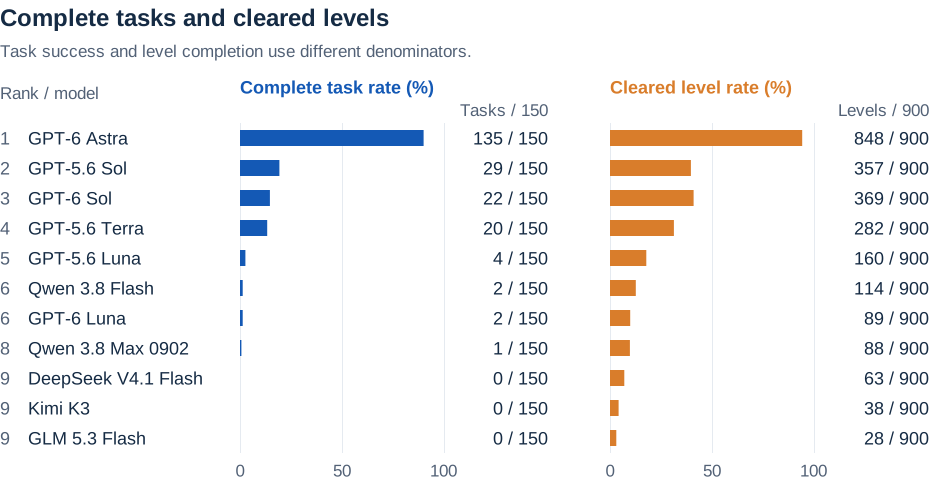
Full wins tell only part of the story.
Each configuration faces the same 150 tasks. A full win clears all six levels; level completion retains partial progress out of 900 offered levels. Equal win counts share a rank.
| Rank | Configuration | Full tasks / 150 | Full rate | Levels / 900 | Level rate | 720 s endings |
|---|
What does a 720-second ending mean?
The six-level curriculum was unfinished when the normal game clock expired. Completed levels still count. The clock includes model-response waiting, tools and gameplay; the ending alone does not establish its cause. Confirmed engineering interruptions were independently reviewed and kept outside the eligible score population.
03 / LOOK CLOSER
Same task. Different stopping points.
Purposively selected matched examples connect scores to unmodified recorded observations.
Terminal panels may show different attained levels. Times shown are authoritative game times; a saved observation may postdate the terminal timestamp. Different settings, serving routes and dates limit model-only causal attribution.
04 / WHAT COMES NEXT
From challenges
to a testable learning loop.
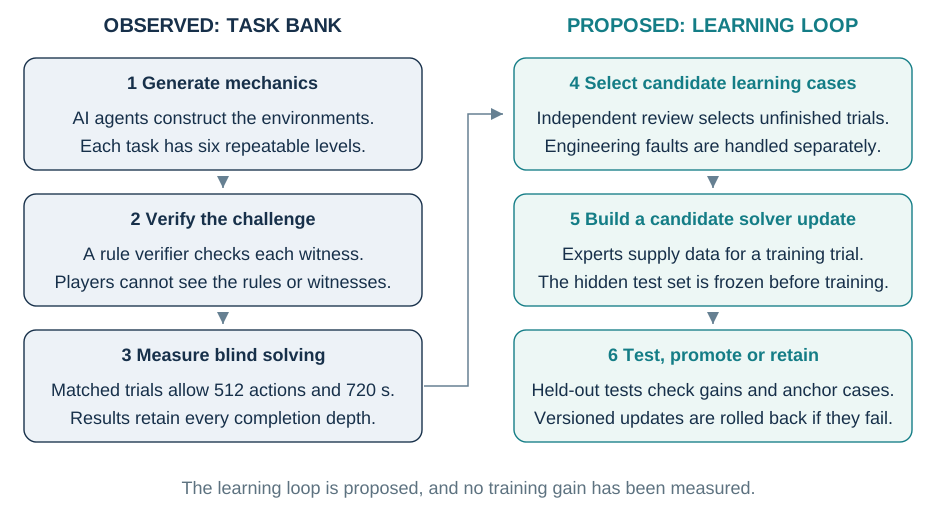
The bank supplies solvable, resettable challenges and verified traces. A future learning experiment can select eligible failures, construct candidate expert data, then test updates on frozen hidden tasks with regression checks.
The current study reports construction and solving outcomes. It does not report a measured training gain.